Make Your Visitor Lead Scores Defensible
Website visitor lead scoring only works if you can explain it. If you can’t say why a visitor got a certain score, teams won’t trust it or use it. That includes marketing, sales, and compliance.
When we say “explainable lead scoring,” we mean three simple things. You can see which signals drove the score, you understand how the model behaves, and you have a clear story a rep can say about any visitor. No guessing and no vague “the model said so.”
Right now, budgets are tight and planning season is intense. When most of your traffic is still anonymous, you need to prove why one visitor is getting fast follow-up while another is not. We’ll walk through model transparency, feature accountability, and rep-visible reason codes, then end with a checklist you can use with any vendor or internal team.
Why opaque visitor scoring fails in the real world
A closed scoring system usually looks like this: you get a single score from 0 to 100, maybe a “hot” or “warm” label, and that’s it. No rules, no feature importance, no hint which behaviors or data points pushed someone into the hot group.
The costs show up fast:
- Sales ignores the scores because they can’t see why a visitor is “95 hot” instead of “62 warm.”
- Marketing can’t debug drops in performance when traffic or identity match shifts.
- Compliance won’t sign off if they don’t know what data fields are in play.
Consider a B2B SaaS company with heavy traffic. Their model flags 30% of weekly visitors as “hot,” but only about 5% of those turn into meetings. Reps start to trust their own routing instead of the score. When that company switches to explainable scoring and tightens the definition of “hot” to the top 10% of visitors, meeting rates rise from roughly 5% to 12% for that group, and reps shift time toward visitors that actually match the ideal customer profile (ICP) and show clear intent.
This matters even more for website visitor lead scoring than for simple form fills. You’re using anonymous sessions, intent signals, and external data stitched together. If no one can explain how those pieces combine, the safest move is to ignore the score.
Demand Model Transparency You Can Actually Use
Model transparency means you can see what kind of model you’re using, what data it learned from, how it performs by segment, and how stable it is over time. “We use machine learning” isn’t an answer.
At a minimum, you should ask for:
- Model description: Is it logistic regression, gradient-boosted trees, or rules on top of a model? Why that choice, given your traffic volume and data mix?
- Performance metrics: Precision and recall at different score cutoffs, not just one top-line accuracy number.
- Segment-level results: Desktop vs. mobile, new vs. returning, paid vs. organic, first-party identified vs. third-party matched.
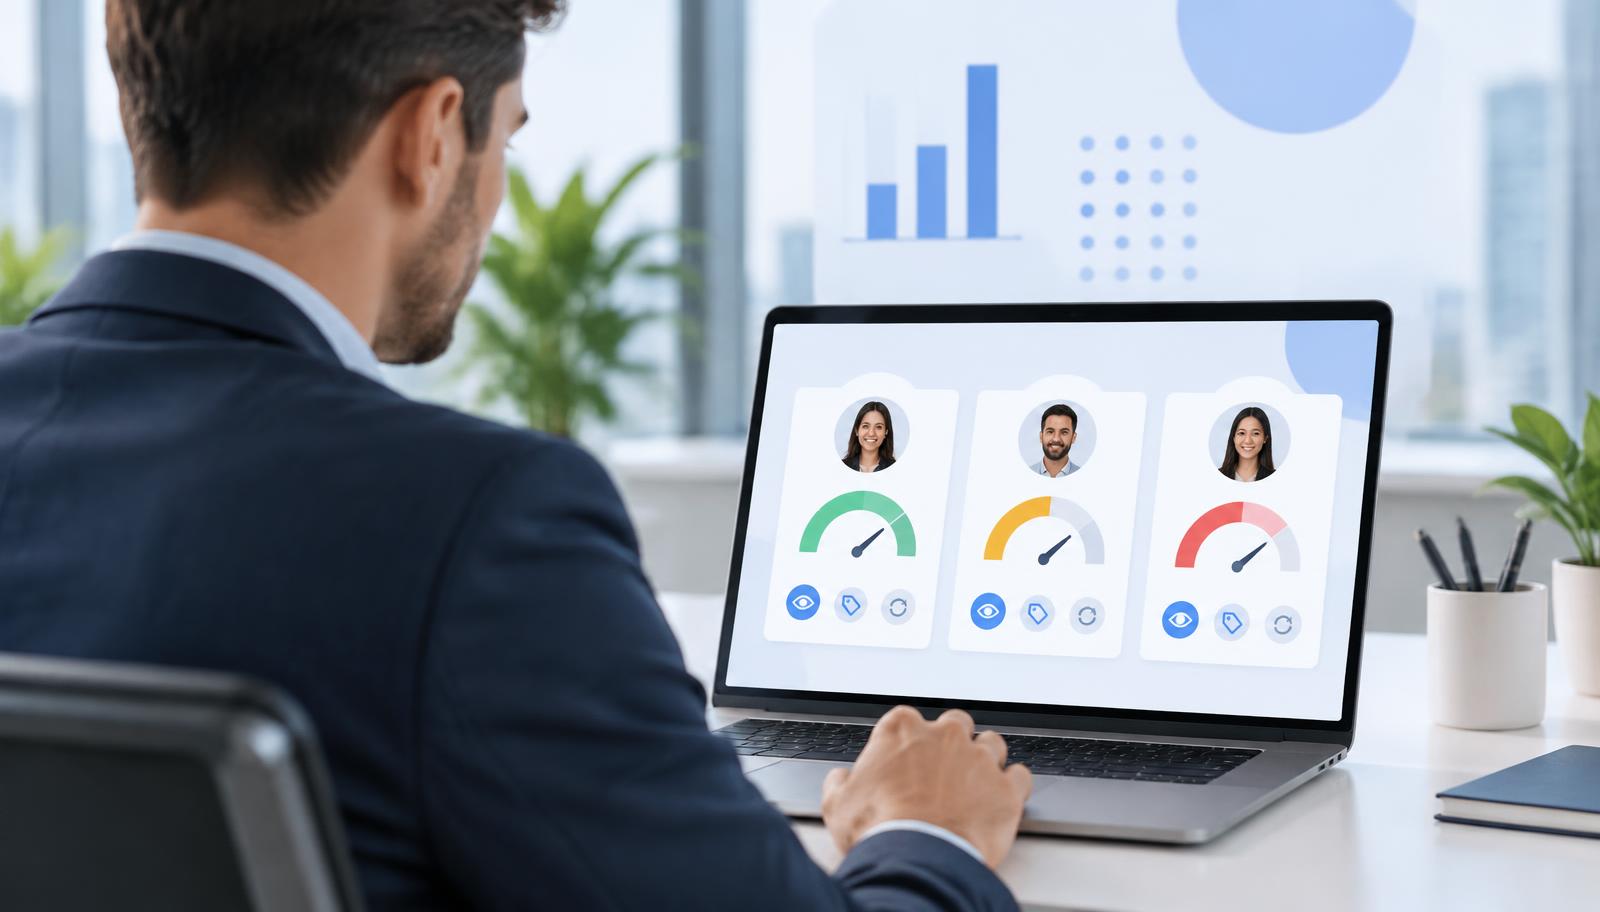
A useful platform will show a transparency report that includes a confusion matrix, area under the curve (AUC), and a lift chart. It should refresh at least monthly so you can see drift. You should also see version history with clear notes like “Removed low-quality title field; hot volume down from 22% to 18%; conversion rate up from 6% to 8%.”
Example: One team noticed that mobile visitor scores had half the conversion rate of desktop, even at the same score band. With a segment-level lift chart, they saw that the model underweighted mobile pricing-page views. After retraining with better mobile features, conversion on mobile “hot” visitors moved from 3% to 7% over a quarter.
Here are simple questions you can bring into a vendor or internal review:
- How often do you retrain, and what triggers a retrain?
- What’s your worst-performing segment, and how do you monitor it?
- Can I see a lift chart for the last quarter, broken out by channel?
If those questions create awkward silence, you’re dealing with an opaque system.
Put Every Feature on the Record
Feature accountability means every data point the model uses is named, sourced, and explained. You should know if more of that feature raises or lowers the score.
For website visitor lead scoring, this is nonnegotiable because you’re mixing:
- Clickstream: pages, time on site, scroll depth, repeat visits.
- Identity: company, email, cookie or device-level IDs.
- Enrichment: firmographics (company size, industry), technographics (tech stack), and buying-stage or segment tags.
Without a clear inventory, you can’t answer basic questions like “Did this score depend on stale firmographic data?” or “Are we using fields legal didn’t approve?”
A solid feature log will show:
- Name and description, for example, “Visited pricing page” or “Employee band 200 to 500.”
- Source and recency, like “IP graph, refreshed weekly” or “CRM sync, nightly.”
- Impact range or importance score, so you know which features matter and roughly how much.
Example: one marketing team assumed a specific flagship ebook was a strong buying signal. When they reviewed feature importance, that asset had near-zero lift on conversion. A behavior like “return visit within 24 hours” had 3x the lift. They shifted nurture and routing rules to focus on recent return visits, and within one quarter, opportunity creation from visitor leads increased by 15%.
Use questions like these during review:
- Can we export a feature list with importance scores?
- Which 10 features drive most of the variance in scores right now?
- What happens if a data source degrades or stops sending data?
Turn Scores Into Rep-Visible Reason Codes
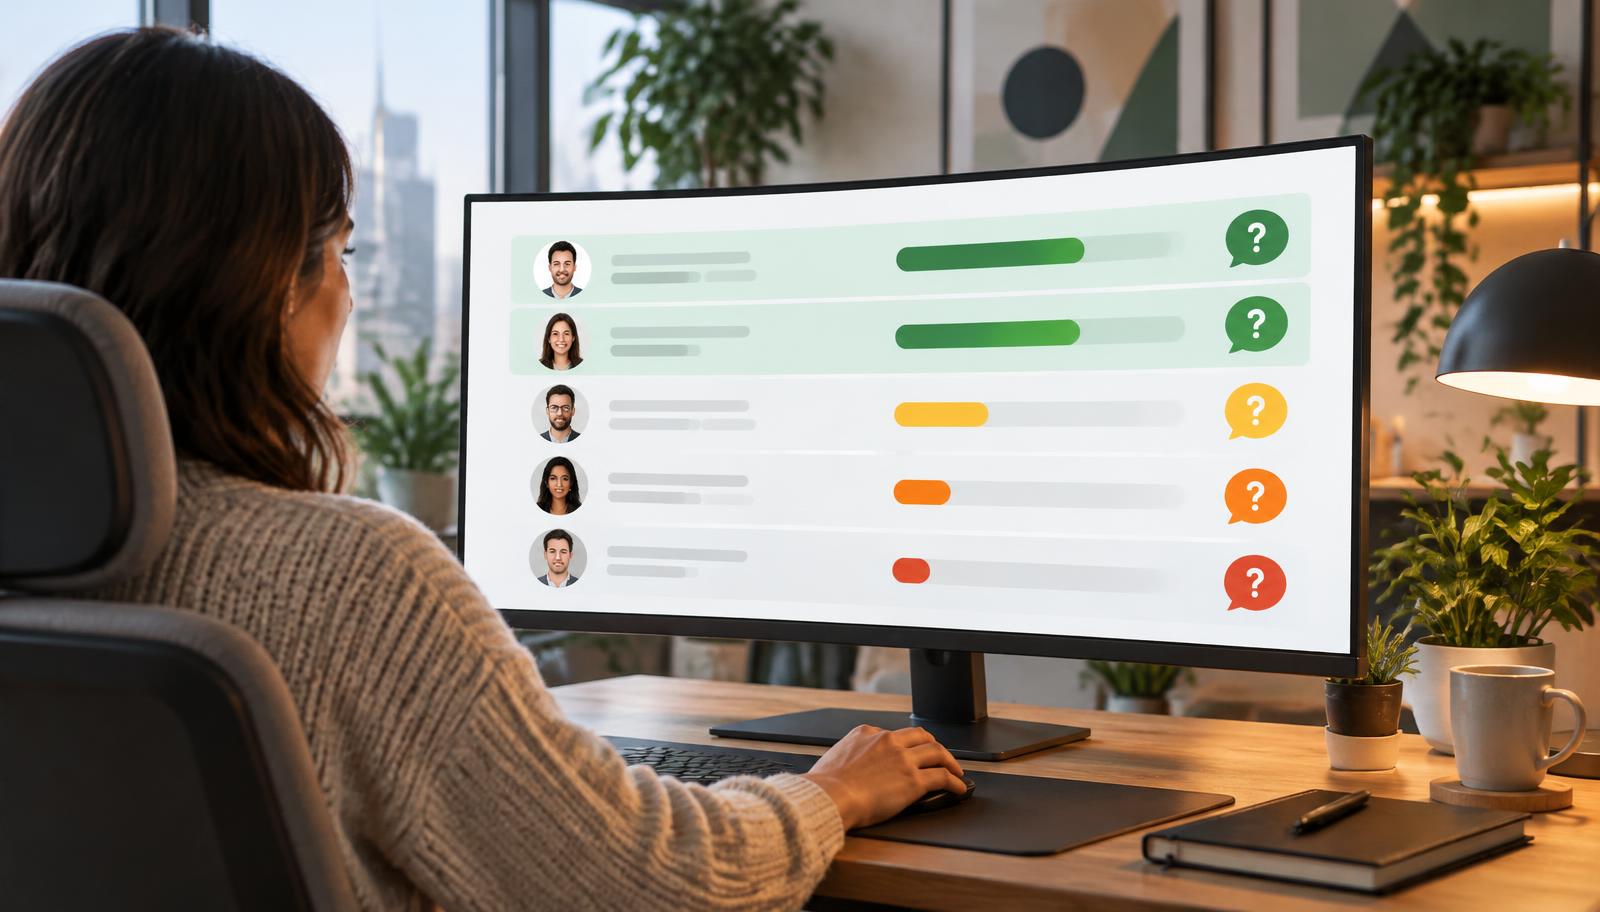
Reason codes are short, human-readable explanations tied to each score. They list the top factors in order of contribution, in plain language. For example: “Repeat visitor from mid-size software company; viewed pricing and integration pages; clicked LinkedIn ad last week.”
Reason codes are the bridge between data science and sales. Instead of “Score: 87,” a rep sees: “High intent; fits ICP size; familiar tech stack; recent pricing and competitive content.” That tells them who to call first and what to say.
Good reason codes usually follow a simple pattern:
- Top three to five drivers only; no full feature dump.
- Grouped by type: fit, behavior, channel, recency.
- Linked to clear actions, like “Visited pricing in last 24 hours,” not vague labels like “high engagement.”
When reason codes show up inside the CRM lead view, reps can tailor outreach fast. A sales development representative (SDR) might write, “I saw you were on our pricing and integration pages yesterday; we help teams your size cut onboarding time.” That line connects directly to the behavior behind the score and tends to lift reply rates on visitor-sourced leads.
To implement this, your data or platform team maps raw features to readable labels, agrees on format and length, then pilots with a small rep group. Feedback from that group will tell you which codes are useful, which are noise, and what to adjust.
Align Scoring With Seasonal and Campaign Reality
Traffic, budgets, and buying cycles change in Q4. Visitor lead scoring needs to reflect that shift, not fight it.
Set-and-forget models break when:
- Anonymous traffic spikes from content syndication or gifting campaigns, and identity match rates drop.
- New seasonal behaviors show up, like event signups or year-end promo clicks.
- Old evergreen behaviors stay overweighted in the model while seasonal intent is underweighted.
Explainable scoring makes this easier to manage. You can define seasonal features like “Clicked Q4 promo banner” or “Viewed budgeting webinar page.” You can use different thresholds for campaign traffic vs. evergreen traffic and label that in reason codes so reps see the context.
In busy months, run quick checks every week:
- Are hot leads from visitor scoring still converting at the rate we expect (for example, 8% to 12% to opportunity)?
- Which features are spiking in use, and are they near the top of the importance list?
- Do reason codes reflect current campaigns, or do they still talk in generic terms?
One marketing team, for example, added “year-end renewal content views” as a feature and surfaced it in reason codes. That pulled customer success into follow-up on those visitors and helped grow expansion pipeline by about 10% from traffic that would have been treated as simple net-new leads before.
Use This Checklist Before You Buy or Rebuild
Explainable website visitor lead scoring isn’t just a data science wish list. It’s a standard you can hold yourself and vendors to. The core pieces are simple:
- Clear model description with live performance metrics.
- Full feature inventory with importance and data-source notes.
- Rep-visible reason codes tied to next actions.
- Seasonal- and campaign-aware behavior, not static rules.
Here’s a quick yes-or-no checklist you can use right now:
- Can you explain, in three sentences, how your visitor scoring works?
- Can a rep see why a visitor is “hot” without asking operations?
- Do you know which 10 features matter most for your scores?
- Do current campaigns show up in scores and reason codes?
- Have you looked at model performance in the last month?
If the answer is no in more than one spot, start small. Pick one active model and add a feature list, or a simple performance report, or reason codes, in your next sprint.
Next step: choose one live visitor-scoring model and schedule a 60-minute review with marketing, sales, and operations. Walk through model transparency, feature inventory, and reason codes against the checklist above. Commit to one concrete change you can ship in the next two weeks that makes your scores easier to explain and easier to trust.
Turn Anonymous Visitors Into Qualified Sales Opportunities
Ready to see which anonymous visitors are most likely to become customers and act on that insight in real time? At DataMoon, we help you turn raw traffic data into clear, prioritized insights with accurate website visitor lead scoring. We work with your existing tools so your team can focus on outreach instead of guesswork. Tell us about your goals and we will help you build a scoring strategy that fits your pipeline.