Better Coverage Starts with a Smarter Match Order
Email and mobile coverage is not just a matter of buying more data. It depends on the order in which we match records, the identifiers we trust, and the rules we use to reject weak matches.
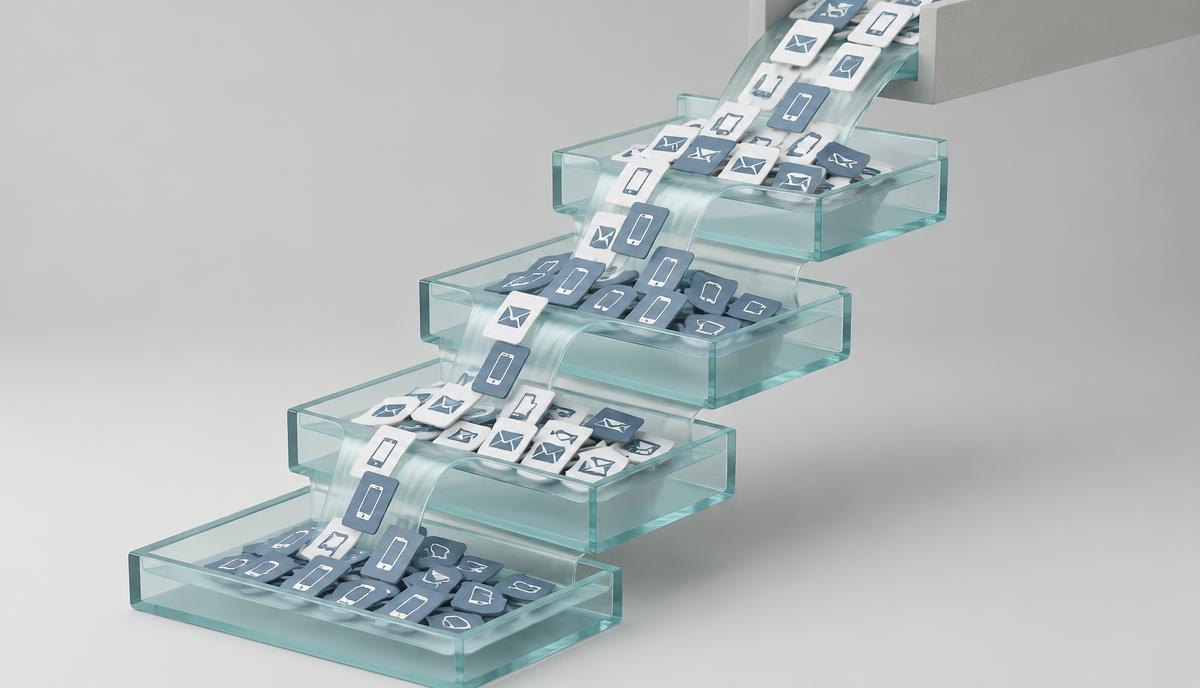
A waterfall is a sequence of identity-resolution steps. We attempt the highest-confidence match first, then move to broader methods only when the record needs more help. That approach matters heading into October and Q4, when stronger contact coverage can expand retargeting audiences, improve abandoned-cart recovery, refresh CRM records, and give outbound teams more usable contacts.
Consider a DTC brand with 100,000 customer records containing names, postal addresses, and partial emails. A structured waterfall can recover verified fields from records with enough signal, without pretending every record is equally matchable. That difference protects the campaigns that follow.
Set the Rules Before You Call an API
A data enrichment API works best when the input file is clean and the match rules are set before submission. First name, last name, physical address, email, phone, IP-derived signals, and hashed identifiers do not carry the same matching value.
Before we send records through a waterfall, we recommend standardizing the file:
- Normalize street addresses, apartment fields, cities, states, and ZIP codes
- Remove duplicate customer records and obvious test entries
- Check email syntax and separate invalid or incomplete emails
- Format phone numbers consistently
- Separate household-level fields from person-level fields
The goal is not to make a messy record look complete. It is to make the available identifiers consistent enough for the system to assess them correctly.
For example, “Jane Smith,” “J. Smith,” and “Jane A. Smith” may all refer to the same customer, but an apartment number or ZIP+4 can determine whether the system should treat them as one person or separate records. A team that leaves apartment fields in an unstructured address line may lose otherwise valid matches or create household-level matches that should not be used for person-level activation.
A deterministic match uses an exact, strong identifier combination. For example, a full name paired with a normalized street address and ZIP code can support a person-level match. A probabilistic match uses several weaker signals to estimate that two records likely belong to the same person.
That distinction should shape your rules. A CRM record with a full name, street address, and ZIP code belongs in a higher-confidence tier. A record with only a first name, city, and company domain may need stricter suppression or a business-focused match path. A data enrichment API should not treat those two records as equal just because both contain text fields.
Rank Identity Signals by Confidence and Consent
Not every identifier deserves the same weight. We generally rank verified first-party identifiers, such as a submitted email address or phone number, above full name and postal address. Device, IP, behavioral, and household signals can still be useful, but they usually belong later in the waterfall and should follow the use case.
A practical hierarchy looks like this:
- Verified first-party email or phone
- Full name plus validated postal address
- Name, address, and household-level signals
- Device, IP, or behavioral signals
- Broader graph-based or modeled relationships
Email and mobile also need separate confidence thresholds. An email may be suitable for compliant marketing activation, while a mobile number may need added governance based on campaign type, consent status, TCPA considerations, DNC screening, and your internal policies.
Recency matters, too. A mobile number tied to a recent, high-confidence record should rank above one that has not been observed or validated for a long time. The same logic applies to email deliverability and engagement signals. More fields are not automatically better fields.
For a retail brand, a recently engaged email address may qualify for an abandoned-cart audience even if the customer’s postal address is older. That same record should not automatically qualify for SMS if the available mobile number lacks the consent documentation or screening required by the brand’s policy. Matching confidence and activation permission are separate decisions, and treating them separately prevents coverage gains from creating channel risk.
If a record has a recently verified email but only a low-confidence mobile match, we would append the email and either flag or suppress the mobile based on the client’s rules. That is disciplined enrichment, not a race to produce the biggest append count.
Use Waterfall Tiers to Protect Match Quality
A useful waterfall gives each tier a clear job. It also gives each tier separate acceptance criteria, allowed output fields, and suppression logic.
For many programs, we recommend a structure like this:
- Tier 1: exact person-level matches using strong, verified identifiers
- Tier 2: strong name, address, and household combinations
- Tier 3: broader graph-based or modeled matches, accepted only for approved use cases
Tier 1 may return both email and mobile when the match and governance rules support it. Tier 2 may return email only unless mobile confidence clears a higher threshold. Tier 3 might be appropriate for audience creation or analysis, but not for direct outreach.
This is where a data enrichment API earns its place in the workflow. Rather than forcing a team to sort records manually, the API can return match status, match tier, confidence information, source metadata where available, and appendable contact fields. Your CRM, audience platform, or outbound workflow can then route each record based on the result.
For example, an agency enriching a client’s lapsed-buyer list might allow exact matches to receive email and mobile appends for approved channels. Household-level matches could feed audience creation only, not direct email or phone outreach. The same file produces different actions because the rules respect match quality, deliverability, and compliance posture.
Measure Coverage, Cost, and Downstream Outcomes
Match rate is only the starting point. A large matched file is not automatically a useful file if appended contacts do not deliver, respond, or convert.
We recommend measuring performance by waterfall tier, not just across the full batch. That lets you see whether lower tiers are creating profitable reach or simply adding record volume with weaker data.
A simple scorecard can include:
- Records submitted and records matched
- Emails appended and mobiles appended
- Accepted records after quality filters
- Activated records by channel
- Revenue or pipeline influenced
- Cost per activated contact
Email deliverability, mobile validity, opt-out rates, audience size, and conversion rate should also sit beside those totals. Each metric answers a different question. Gross coverage tells you how much data came back. Accepted coverage tells you how much met your rules. Activation and conversion tell you whether the data helped the business.
To isolate the value of each tier, compare matched records against a holdout group that did not receive the appended field or audience treatment. A DTC brand might measure incremental revenue per 1,000 activated contacts, while a sales team might measure meetings booked per 1,000 records. If Tier 3 expands an audience by 20% but produces no measurable lift in purchases or pipeline, it may still be useful for analysis, but it should not receive the same budget or activation rules as Tier 1.
A B2B sales team may find that Tier 1 and Tier 2 email matches drive most booked meetings, while lower-tier mobile matches produce limited pipeline. That finding gives the team a clear decision: tighten mobile rules, shift budget toward better-performing tiers, and use the data enrichment API where it improves sales efficiency rather than where it merely adds contacts.
Build a Waterfall You Can Improve Every Week
The strongest enrichment programs do not chase the largest possible append count. They build a clear match order, set confidence thresholds by field, and measure whether appended data improves actual campaign and revenue outcomes. At DataMoon, we use data graph and waterfall match logic to keep usable emails, mobile numbers, activation rules, and performance measurement in the same operating view.
On Monday morning, audit the identifiers already in your CRM or customer file. Define which tiers can append email, mobile, or both. Set suppression rules for low-confidence, outdated, or noncompliant records, then review performance by tier after each activation cycle. A waterfall should keep getting sharper as you learn what your best records actually do.
Turn More Customer Records Into Reachable Audiences
DataMoon helps you turn incomplete customer files into usable email and mobile coverage without treating every record the same. Use our data enrichment API to apply waterfall logic, append the fields your campaigns need, and keep match quality visible by tier. We’ll help you build an enrichment workflow that supports stronger audience activation, cleaner CRM records, and more accountable performance reporting.