Turn Low Match Rates Into a Competitive Edge
Low match rates in Customer Match on Google, Meta, and LinkedIn waste budget. The problem usually isn’t your media plan. It’s identity resolution issues, weak inputs, and missing consent flags. When match rate climbs, every campaign you already run gets stronger without touching creative or bids.
Customer Match is simple on paper. You upload customer identifiers like email, phone, or address. The platform matches them to user accounts so you can target or suppress those people. Match rate is the multiplier: moving from a 30%, 40% match rate to 60%, 70% on the same list often doubles real reach and conversions.
As you go into Q4 and early-year planning, small gains here matter. A bump of even 5, 10 points in match rate on your best audience can move revenue without building new funnels or audiences. We’ll walk through identity resolution, hashing, consent, and offline-to-online stitching from the lens of a real-time customer data platform and what you can do in the next 90 days.
Why Match Rate Is the Hidden Performance Multiplier
Each platform runs its own version of Customer Match, but the idea is the same. You give:
- Google: emails, phones, and postal addresses
- Meta: emails, phones, and sometimes full names and ZIP Codes
- LinkedIn: work emails, personal emails, company, and other B2B details
The platform lines up your identifiers with user accounts. If you upload 1 million rows and only half match, your actual reach is 500,000 people, no matter how hard you push budget. If another brand gets a 70% match rate on the same list size, they reach 700,000 people and have better odds of winning each auction.
A few key points many teams miss:
- Platform match rates reflect how many uploaded rows matched at least one ID.
- Email-only files often underperform mixed files that include email, phone, and address.
- Bad formats count as uploads but almost never count as matches.
Two myths cause most trouble.
First myth: “We just need more data.” Often you don’t. You need better-structured emails and phones, not more half-broken records. A 1 million-row file at 35% match rate is weaker than a 600,000-row file at 70%.
Second myth: “It’s a platform problem.” Most of the time, the issue lives inside your CRM, exports, and scripts.
Example: a retailer that only uploads emails into Google, many of them unverified or old, sees a 30% match rate. When that team starts validating email formats, removes dead records, and adds well-structured phone numbers, match rate moves into the 55%, 65% range. Media budget doesn’t change, but revenue does, because more real customers are now targetable or suppressible.
Fix the Inputs With Data Hygiene That Actually Moves Match Rate
Before identity graphs, you need basic data hygiene. Three input dimensions matter most:
- Identifier completeness: do you have email, phone, and postal where possible?
- Identifier quality: are they valid, current, and active?
- Identifier consistency: does the same person look the same across systems?
A basic hygiene checklist:
- Emails: normalize to lowercase, trim spaces, remove obvious fakes and role accounts, and run simple checks for valid format.
- Phones: store in E.164 format (country code plus number, no dashes or brackets).
- Addresses: use standard casing and abbreviations, and keep fields consistent across systems.
When teams run email validation, the number of truly matchable records often climbs. You might end up with 15%, 25% fewer total rows because you drop junk, but the share of what remains that matches on Google, Meta, and LinkedIn can jump by 10, 20 points.
Example: a subscription brand starts with 800,000 CRM records and a 45% match rate on Meta. After removing bounced emails, fixing case and whitespace, and standardizing country codes on phones, they drop to 620,000 records. The next upload hits a 63% match rate. Even with fewer rows, they see ~75% more matched profiles and lower CPA on retargeting.
Build an Identity Graph Instead of Shuffling CSVs
Identity resolution ties your identifiers together. An identity graph links many identifiers to one person or account. There are two main approaches:
- Deterministic: clear matches like same email, same login ID, same phone.
- Probabilistic: softer signals like shared device, IP, or behavior patterns, used carefully and with compliance controls.
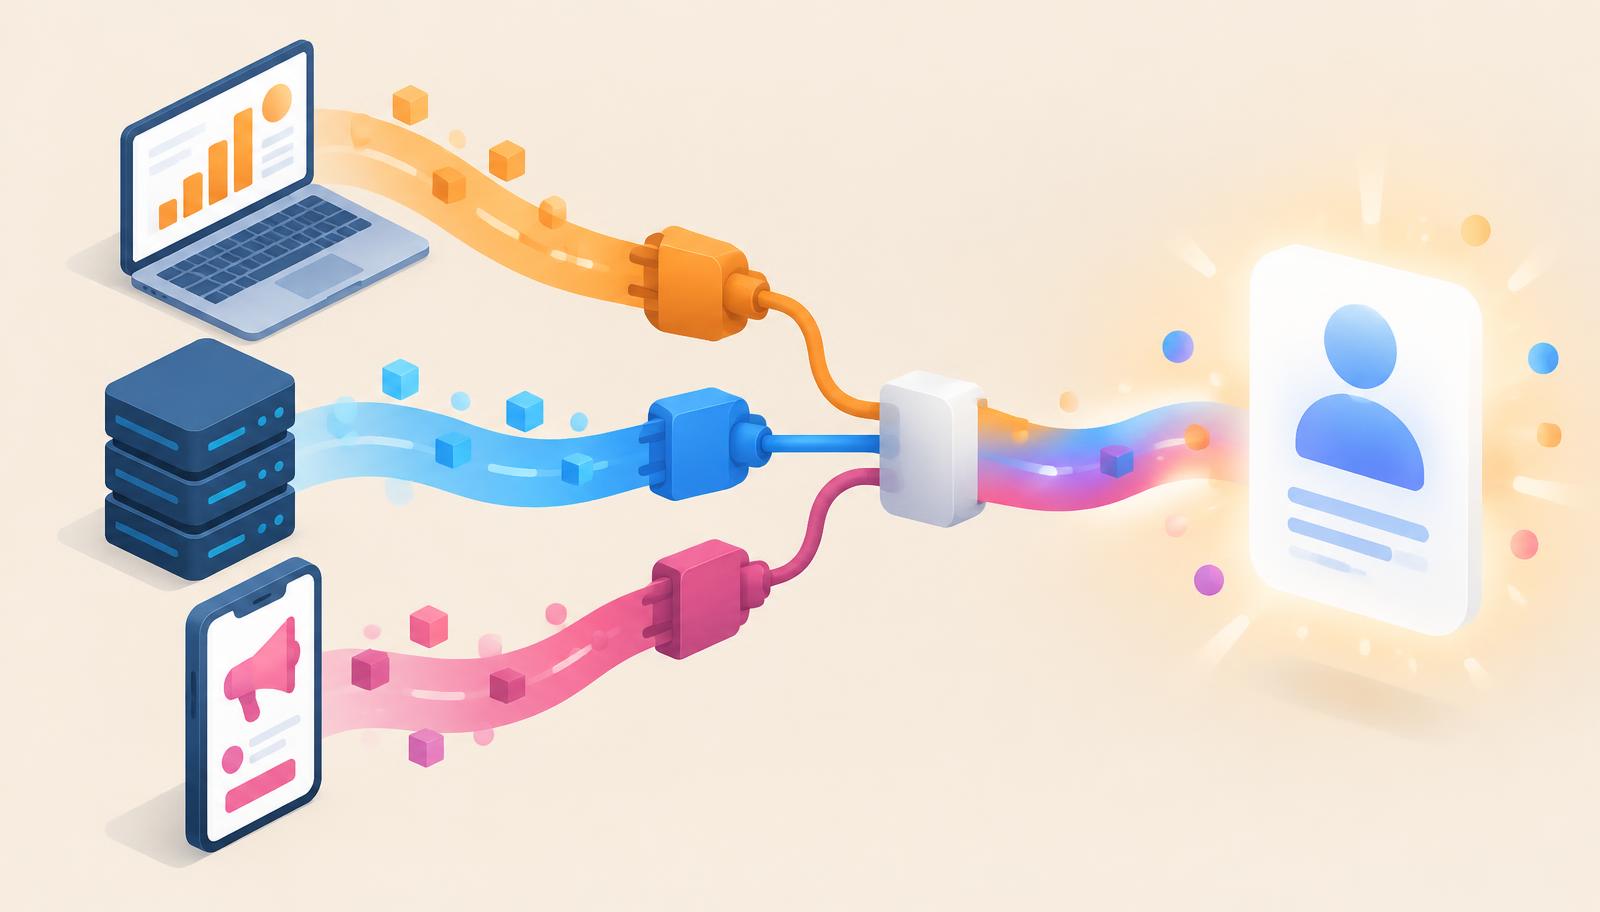
Flat CSV exports treat every row like its own person. A real-time customer data platform does something different. It:
- Ingests data from CRM, e-commerce, POS, support tools, and offline sources.
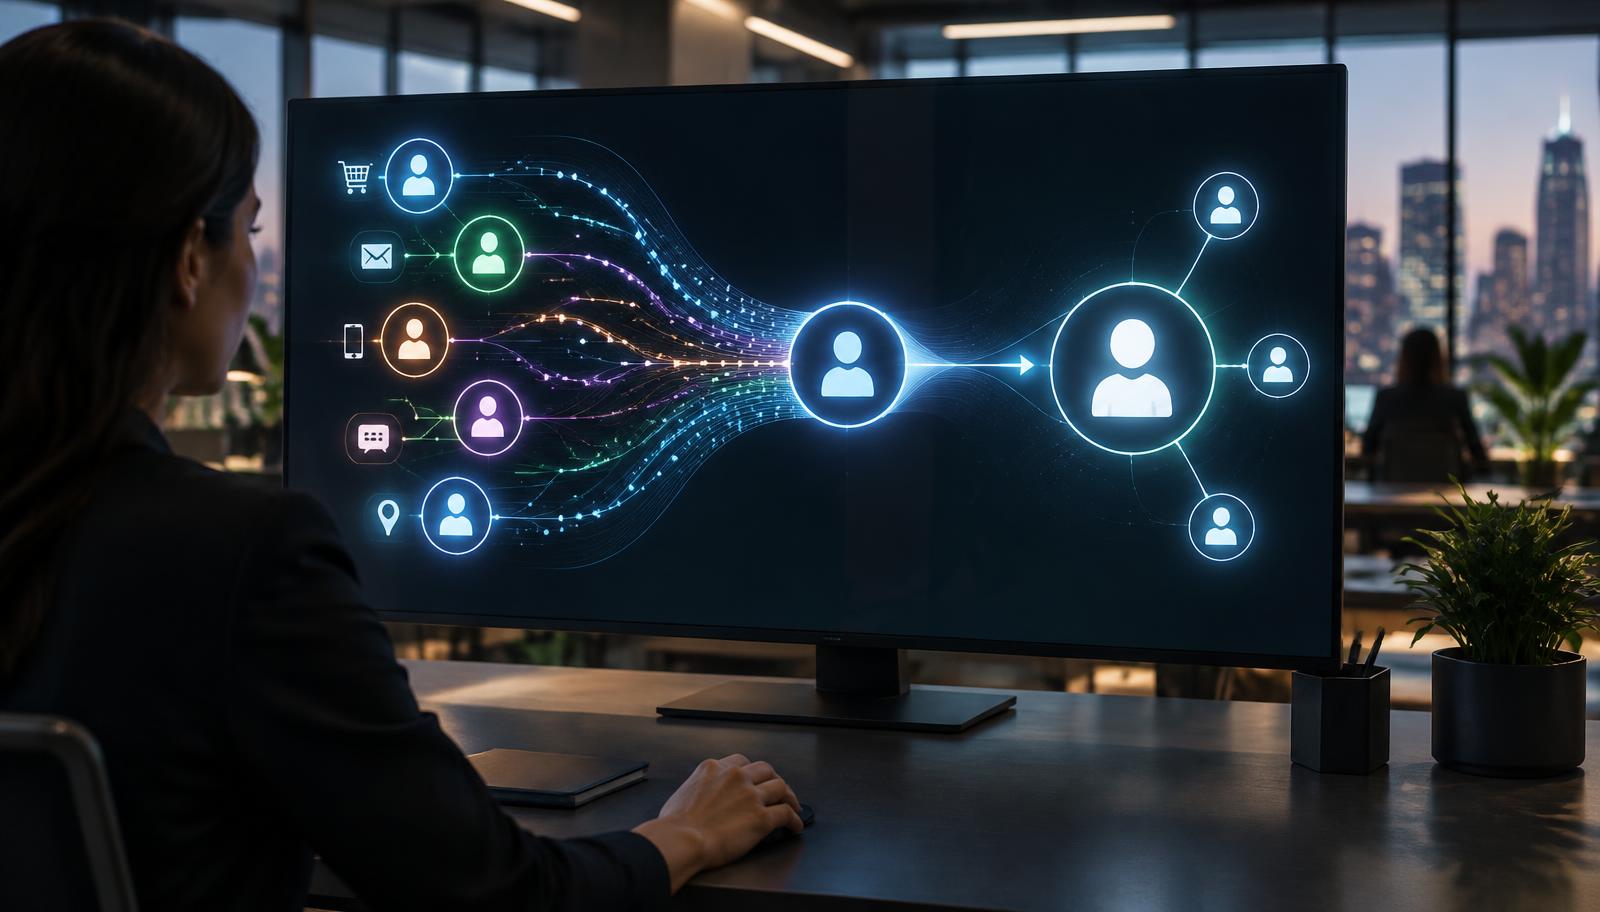
- Resolves those events to a stable person or account ID.
- Stores the best known email, phone, and address per person.
This helps match rate because:
- Duplicates get merged, so you stop uploading the same human three different ways.
- Each person record carries more identifiers, which gives Google, Meta, and LinkedIn more chances to find the right account.
- Suppression lists get cleaner, which cuts wasted impressions on people who already converted or opted out.
Example: many brands discover that 10%, 30% of their “unique contacts” are actually duplicates or fractured views of the same people. One omnichannel retailer unified online logins, loyalty IDs, and in-store receipts. Their total “unique people” count dropped from 5.2 million to 3.9 million. But the average identifiers per person jumped from 1.3 to 2.1, and Customer Match rates on Meta rose from 38% to 62% within two months.
Get Hashing, Formatting, and Offline Stitching Right
Good identifiers still fail if you hash or format them wrong. The major platforms expect:
- SHA-256 hashing for emails and phones when you don’t send plain text.
- Normalized inputs before hashing, like lowercase emails and E.164 phones.
- Clean strings with no extra spaces or stray characters.
Common mistakes that quietly crush match rate:
- Double hashing because one system already hashed and another script hashes again.
- Mixing hashed and plain text in the same column.
- Exporting in odd encodings that add invisible junk characters.
Before you upload a big file, you should:
- Normalize everything the same way every time.
- Apply SHA-256 exactly once to fields that require hashing.
- Test a small sample against platform tools or APIs to confirm formats are accepted.
Example: a B2B team was seeing 25%, 30% match on LinkedIn from a high-intent lead list. A quick check showed emails were already hashed in the warehouse, then hashed again in a connector. After removing the extra hashing step and forcing UTF-8 encoding, match rate climbed to 55% on the next 50,000-record test.
Offline-to-online stitching is the other half of this.
Store visits, call center chats, and event check-ins often capture high-intent customers. Without stitching, those people never show up in digital Customer Match.
A working offline-to-online play usually looks like this:
1) Capture at least email and phone at checkout or interaction, with address as a helpful backup.
2) Send those identifiers into a real-time customer data platform tied to a unified person ID.
3) As that person logs in on web or app later, link digital identifiers like cookies or app IDs.
4) Push stitched audiences into Google, Meta, and LinkedIn for retargeting, suppression, and lookalikes.
Example: over a peak-Q4 weekend, a shopper buys in-store and only shares a phone number. That phone matches an existing email in your identity graph. Within a day, the combined record joins the “Holiday Purchasers” audience. That person is pulled out of prospecting and added to cross-sell instead. In pilots like this, brands often see 10%, 15% of in-store buyers become addressable in digital within a week, with 20%, 30% lower CPA on those stitched audiences.
Improve Match Rates While Respecting Consent
All of this only works if you respect consent. Here, consent means clear permission to use personal data like email, phone, or address for marketing and paid media audiences.
Good consent management covers:
- Where consent is captured: web forms, POS, events, or support.
- What channels the person agreed to: email, SMS, paid audiences.
- How opt-outs flow across systems, including Customer Match lists.
Privacy-first doesn’t have to mean low match rate. Clear consent records often lead to:
- Fewer complaints and less list churn.
- Stronger engagement that platforms notice, which can support better delivery.
A practical approach:
- Map every consent source and feed those records into a central identity graph.
- Use simple language that mentions custom audiences and platform-based advertising where needed.
- Honor opt-outs quickly across all channels, including any uploads to Google, Meta, and LinkedIn.
Example: one B2B team tightened consent and removed non-consented records from LinkedIn lists. List size dropped by about 20%. Click-through rate rose by 30%, and cost per qualified lead fell by 18% over the next quarter. That’s the trade you’re aiming for: slightly smaller, much higher quality.
Put It Together in a Simple 90-Day Match Rate Plan
You don’t need a giant replatform to fix match rates. You need a clear sequence and a steady hand. A simple 90-day plan could look like this:
1) Baseline: document current match rates on Google, Meta, and LinkedIn for 3, 5 key audiences and identifier mixes. Capture current reach, CPA, and ROAS for reference.
2) Audit: inspect identifier completeness, formats, duplicates, and consent in your CRM, marketing automation tool, and warehouse. Flag the top three failure patterns (for example, formatting issues, duplicates, missing consent flags).
3) Identity graph: either turn on your real-time customer data platform or work with IT to define a unified person ID and connect core systems. Start with CRM, e-commerce, and POS.
4) Standards: agree on global rules for normalization, hashing, and consent flags for all exports and connectors. Document them and make them the default in your pipelines.
5) Offline stitching: make sure POS, events, and sales systems send data into the identity graph and onward to platforms at least daily. Prioritize your top 1, 2 revenue-driving offline sources first.
6) Test: run A/B tests with “old” vs. “cleaned and stitched” audiences and track match rate, reach, CPA, and ROAS. Aim for at least a 10-point lift in match rate on one core audience in the first 90 days.
Most teams starting from messy data but decent scale can raise match rates on core audiences within a season or two. Teams that already have strong processes can still squeeze out gains that matter during peak periods.
Next step: pick one high-value audience (for example, recent purchasers or high LTV customers) and run the full process on that segment first. Baseline match rates, fix inputs, standardize hashing, and stitch offline touchpoints. Once you see the lift there, roll the same playbook across the rest of your program so Customer Match becomes a repeatable competitive edge instead of a black box.
Turn Real-Time Customer Signals Into Revenue Faster
If you are ready to turn fragmented event streams into a single, actionable view of every customer, our real-time customer data platform is built to do exactly that. We help you connect data across channels, keep profiles continuously up to date, and trigger the right experience in the moment. Talk with our team at DataMoon to see how quickly you can get from raw events to measurable lift in retention and revenue.