Prospecting automation only works if your data can be trusted. If you're running B2B prospecting automation, the biggest hidden leak is usually not your messaging; it's broken data and quiet routing failures. When you can't see what's happening across your CRM, enrichment, and intent tools, you lose deals long before your team ever sends an email.
In simple terms, prospecting automation observability means having clear checks, alerts, and service levels around the data that feeds your system. Every week, you should know if your target list, contact coverage, and intent signals look healthy, or if something slipped. This matters even more in Q4, when holidays, budget cycles, and noisy markets make signals jump around. We'll walk through a practical playbook you can actually run.
Make Prospecting Automation Observable, Not Mysterious
Most teams treat their data like a black box. Leads go in, some meetings pop out, and when numbers dip, everyone blames messaging or the SDR team.
A better way is to treat data like an operating system with health checks. Prospecting automation observability covers three simple ideas:
- Signal coverage checks so you know how complete your targets and contacts are
- Drift detection so you spot changes in enrichment or intent data before they hurt results
- Alerts and SLAs so the right person fixes issues before they hit revenue
In Q4, schedules get messy, campaigns stack up, and intent patterns change. That's when you want monitoring in place, before you set next year's pipeline targets.
Map the Prospecting Data Supply Chain End to End
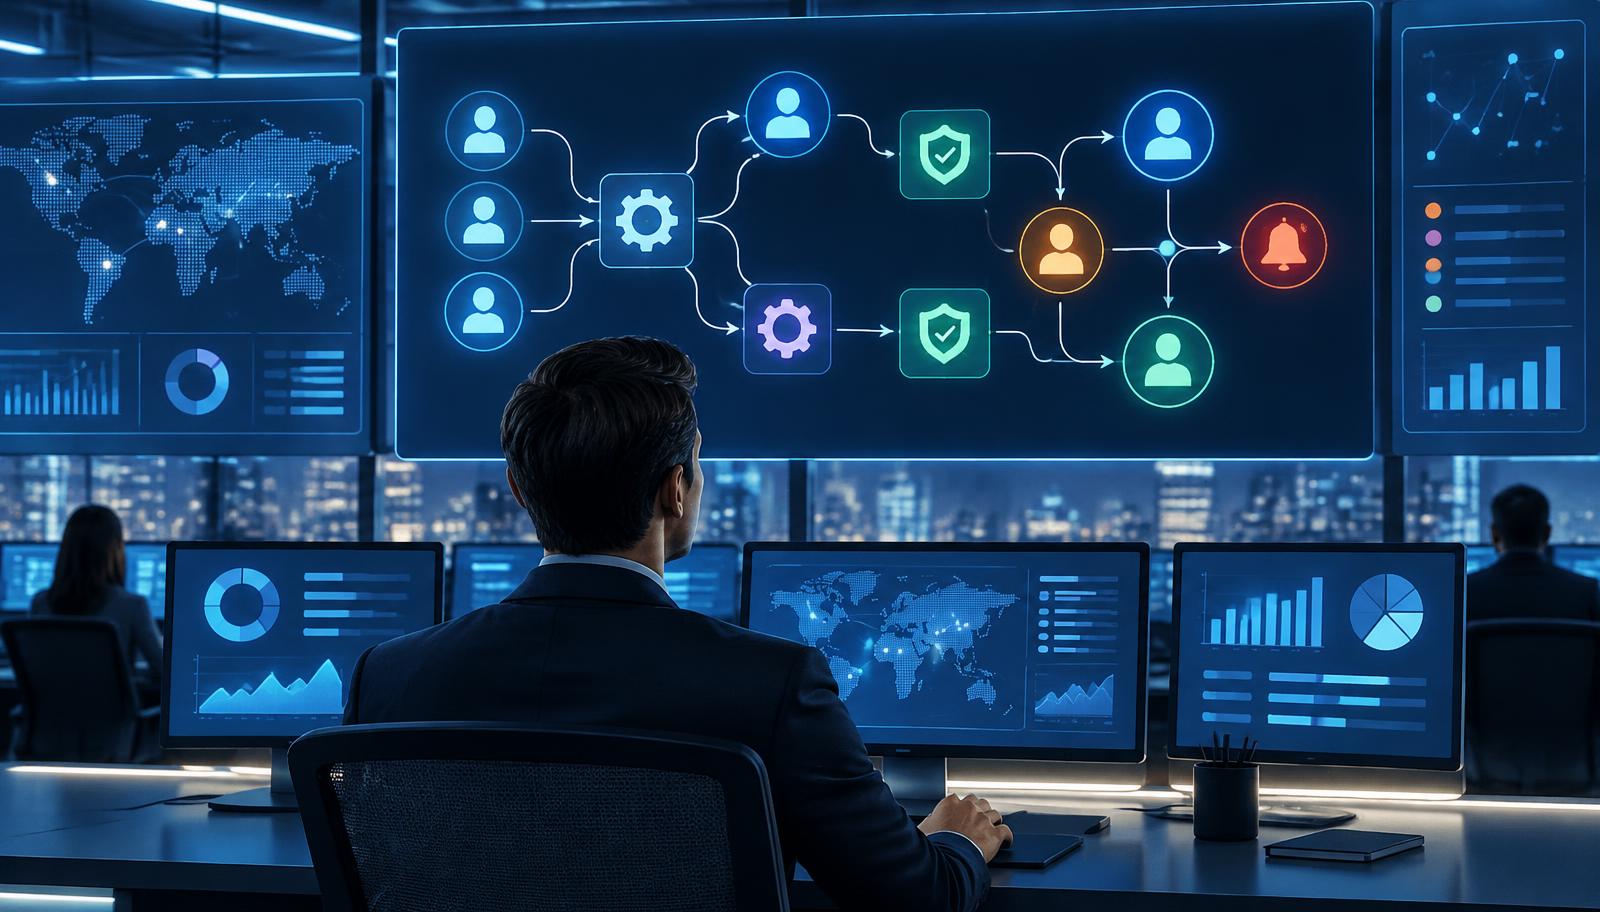
You can't monitor what you haven't mapped. Start by sketching the full path from target account to outbound touch.
Most B2B prospecting flows look like this:
- CRM and MAP hold accounts, contacts, and workflows
- Data providers enrich firmographics, technographics, and contact details
- Intent tools and behavior data show which accounts are actually active
- Activation tools like sequencers, ad platforms, and sales tools push touches
Each time a record jumps from one system to another, you have a data hop. On every hop, you can lose fields, misalign IDs, or skip records. A large TAM list might begin at full coverage in your warehouse, then arrive in your sequencer with only a slice of accounts carrying both a usable contact and an intent score.
The first asset you need is a simple diagram of every hop where:
- Accounts or contacts are created
- Fields are enriched or changed
- Signals like intent or activity are attached
- Records can be dropped or blocked
Once you have that, you know where to put your checks.
Define the Right Signal Coverage Metrics to Watch
Signal coverage is the share of your target universe that has usable information. If you care about industry, buying role, and intent, then coverage tells you what percent of your ICP has those fields filled.
You can start with a few core coverage metrics:
- Target account coverage: what percent of your ICP is in CRM
- Contact coverage: how many contacts per account, in the right roles
- Intent coverage: percent of accounts with at least one recent signal
- Enrichment coverage: emails, phones, titles, company size, technology stack
You don't need perfect coverage to win, but you do need a healthy range. For example, many teams treat something like 80, 90% of their ICP in CRM as healthy, and anything below 60, 70% as a failure line that should trigger a fix.
Here's a simple pattern. A team checks Tier 1 accounts and sees only a small slice with recent intent data. They add another intent source, fix domain mapping, and within a couple of months, the share of active Tier 1 accounts jumps from about 30% to more than 60%. Reply rates follow. That's coverage turning into real pipeline.
For each metric, define:
- A healthy range: where you're comfortable
- A warning zone: where you watch closely
- A failure line: where alerts must fire
Build Drift Detection for Enrichment and Intent Data
Even if coverage looks good, drift can quietly wreck you. Drift means your data behaves differently over time without a planned reason like a new campaign or list change.
Watch for enrichment drift like:
- Match rate drops: a big slide in how many new records get enriched
- Field sparsity: a spike in missing titles or phone numbers
- Value skew: your ICP shifts on paper, for example far more "small business" than expected
Intent data drifts in different ways:
- Normal seasonality: some categories spike at year-end, others slow in summer
- Vendor gaps: a tracking or cookie-sync issue can tank signals
- Domain mapping errors: traffic gets logged under the wrong company
A simple example: late in Q4, you see demo page visits fall a lot in one week. Drift checks show form fills and traffic are steady. That points to a tracking or URL change, not a demand problem. Fix the tracking, and the signal comes back fast.
You can keep drift checks simple:
- Use rolling 4-week baselines for key metrics
- Flag changes bigger than a set percent up or down (for example, 25, 30%)
- Break results by region, segment, and source to see where the issue sits
- Backtest alerts on the last few quarters so you avoid noisy fire drills
Turn Observations Into Alerts, SLAs, and a QA Checklist
Dashboards alone don't protect pipeline. People do, when they get the right alerts with clear expectations.
Set three alert types:
- Urgent: investigate within 24 hours, for example sync failures or giant volume drops
- High priority: fix within a few days, like a slower match rate or a rising queue of unmapped accounts
- Informational: weekly or monthly summaries on coverage trends
Examples of practical thresholds:
- CRM sync volume drops more than a set share in a day (for example, 40, 50%): urgent
- Enrichment match rate falls by a clear step week over week (for example, from ~80% to ~60%): high priority
- Intent volume shifts far from baseline with no planned campaign: review
Tie each alert to an owner:
- Marketing ops owns alert rules and first response
- Data or RevOps owns deeper source checks
- Sales ops owns routing and territory changes
Then layer a lightweight QA checklist on top. A short weekly routine can catch most quiet failures.
Weekly checks:
- New record volume by source vs recent weeks
- Enrichment match rate for net-new records
- Intent signal counts by vendor and account tier
- Share of new leads routed within 24 hours
Monthly checks:
- TAM coverage: how many ICP accounts are active in at least one channel
- Buying group depth by segment
- Email and phone performance by source
- Conversion rates by data quality, for example enriched vs not enriched
When teams see that enriched, well-signaled leads convert at a higher rate, they naturally start building rules like "no Tier 1 lead goes to sales without a full enrichment pass."
Put the Playbook Into Motion
You don't need a huge project to get prospecting automation observability in place. Start by mapping your data hops, set a small set of coverage and drift metrics, and add a weekly QA checklist.
Once you see how often quiet data issues show up in those checks, you can tighten your alert thresholds and SLAs. Over a couple of quarters, you should see fewer surprises in your pipeline and a clearer link between data quality and booked meetings.
Turn Your Prospect Lists Into Qualified Sales Conversations
Stop losing hours to manual research and outreach when you could be talking to decision-makers instead. With DataMoon, you can use our B2B prospecting automation to consistently identify, qualify, and engage high-value accounts. We help you connect your data, refine your targeting, and trigger personalized outreach at scale. If you are ready to shorten your sales cycle and keep your pipeline full, reach out to our team to see what this looks like in your environment.